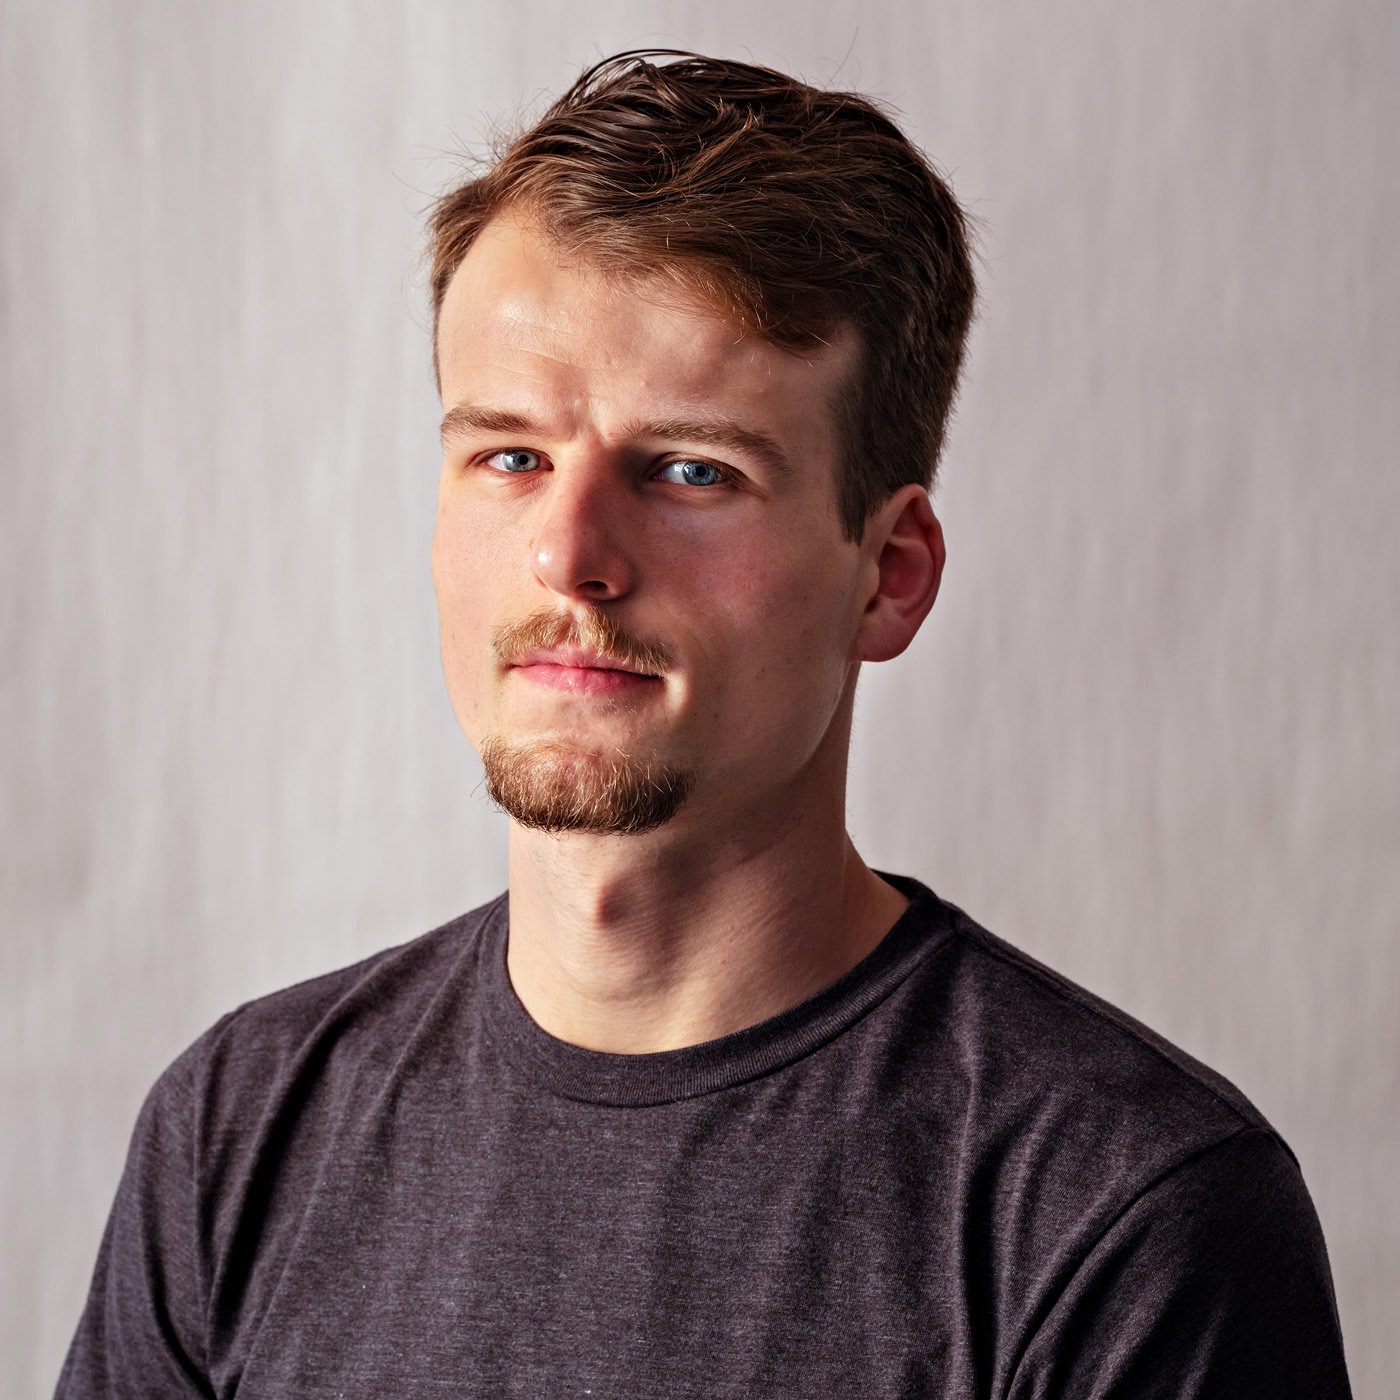
Andreas Haupt
AI Institute Fellow-in-Residence, Schmidt Sciences
Digital Fellow, Stanford Digital Economy Lab
Technology and Human Rights Fellow, Harvard Kennedy School
Andreas Haupt is an AI Institute Fellow-in-Residence at Schmidt Sciences, a Digital Fellow at the Stanford Digital Economy Lab, and a Technology and Human Rights Fellow at the Harvard Kennedy School. He studies how algorithmic systems represent and are evaluated against diverse human preferences, using methods from microeconomic theory, structural econometrics, and reinforcement learning. His work has been published in AI venues such as NeurIPS and ICML, in computer science venues such as ACM EC, ACM RecSys, and ACM FAccT, and as a lead article in the American Economic Review. He has served as an area chair at ICLR, ICML, and AAAI. He earned a Ph.D. in Engineering-Economic Systems from MIT in February 2025 with a committee evenly split between Economics and Computer Science. Prior to that, he completed two master’s degrees at the University of Bonn—first in Mathematics (2017) and then in Economics (2018), with distinction. He has worked on competition enforcement for the European Commission’s Directorate-General for Competition and the U.S. Federal Trade Commission, and taught high school mathematics and computer science in Germany before his Ph.D. He remains committed to education and scholarship, most recently as a co-author of a textbook on Machine Learning from Human Preferences, forthcoming with Princeton University Press.
280-character bio
Andreas Haupt is an AI Institute Fellow-in-Residence at Schmidt Sciences and a fellow at Stanford's Digital Economy Lab and Harvard Kennedy School. He studies how AI systems represent and are evaluated against diverse human preferences, publishing in NeurIPS, ACM EC, and the AER.Tagline
Use AI to Learn about People's PreferencesPublications
A full publication list is available as pdf and BibTeX, and a more complete list on Google Scholar. ‡ indicates equal contribution or alphabetic author listing, † equal supervision. Only published work is shown by default; select another type, or All types, to see the rest.
Welfare, Improvability, and Variance: A Principal-Agent Approach to Optimal Benchmark Item Aggregation
A. Haupt‡, J. Hartenstein‡, A. Reuel, M. Kochenderfer, S. Koyejo
Advances in Neural Information Processing Systems (Evaluations and Datasets Track), 2026.
In brief
A benchmark is reported as a measurement but works as an incentive: once labs optimize against it, the weight on each item steers effort. We model benchmark aggregation as a multitask principal–agent problem. The optimal item weights have a closed form, v* = (M + rΣ)−1Mw—higher for items that matter for welfare (w) and that effort can improve (M), lower for noisy items (Σ) when the lab is risk-averse (r). On the OLMES suite, with welfare weights from workers' own task ratings, all 52 mathematics items are Pareto-dominated by general-knowledge items under a pro-worker welfare definition, and only ~6% of the suite's "automation loading" falls on activities workers want automated. Evaluation designers should publish why each item carries the weight it does.
Reward Bias Substitution: Single-Axis Bias Mitigations Redirect Optimization Pressure
M. Lamparth, D. Fein, A. Haupt, M. Hussing, M.J. Kochenderfer
Advances in Neural Information Processing Systems, 2026.
In brief
Fixing one bias in a reward model (length, sycophancy, style) can simply redirect optimization pressure elsewhere. We prove that success, substitution, and overcorrection are indistinguishable under the audit distributions on which mitigations are usually reported—even with an oracle true reward. Empirically, a length penalty under GRPO shifts pressure into overconfidence with lower factual accuracy, and a published length-debiasing operator's bias reappears under best-of-n sampling for three of four state-of-the-art reward models. Prescription: evaluate under the policy-induced distribution and track several biases at once.
Position: AI Development Should Prioritize Cognitive Security
B. El, S. Su, A. Pappu, P. Yin, J. Heng, E. Heng, R.Z. Wang, A. Haupt†, J. Zou†
Advances in Neural Information Processing Systems (Position Paper), 2026.
Contextually Private Mechanisms
A. Haupt‡, Z. Hitzig‡
American Economic Review 116 (9), p. 3223-3262 (Lead Article), 2026.
In brief
Mechanism design usually asks what to implement and models the mechanism as a one-shot report of types. This paper studies the extensive form instead: a protocol asks participants questions one at a time, and what it learns depends on which question it asks, of whom, and when. A protocol violates contextual privacy when it tells two people apart who would have received the same outcome anyway. Violations are unavoidable exactly when agents are collectively, but not individually, pivotal. Beyond that, the order of questions is a design choice: delaying a question until its answer is needed for the outcome means fewer people are told apart for no reason, so delay improves privacy, and different extensive forms of the same allocation rule can differ sharply in how much they learn. The paper connects auction theory to Helen Nissenbaum's contextual integrity: "information not needed for the outcome" becomes a theorem about protocols.
Machine Learning from Human Preferences
S. Truong‡, A. Haupt‡, S. Koyejo‡
Princeton University Press (forthcoming)
Don't Walk the Line: Boundary Guidance for Filtered Generation
S. Ball, A. Haupt
International Conference on Machine Learning, 2026.
Bruno: An AI Product Manager for Scientists
A. Haupt‡, P. Ranganathan‡
ICML Workshop on AI for Science (Best AI Scientist Award), 2026.
The Collapse of Heterogeneity in Silicon Philosophers
Y. Shi, A. Haupt
ACM Conference on Fairness, Accountability, and Transparency, 2026.
In brief
Can a language model stand in for an expert panel? We tested seven models against 277 professional philosophers and the PhilPapers survey (N = 1,785). Models reproduce individual positions tolerably, but they over-correlate judgments across questions, manufacturing consensus where the profession disagrees—partly a "specialist effect": the model assumes specialists in a domain share views. For anyone using "silicon samples" as proxies for publics, the heterogeneity collapses exactly where it matters.
Discussion of "The ICML 2023 Ranking Experiment" by Su et al.
A. Haupt, S. Koyejo
Journal of the American Statistical Association 121 (554), p. 853-854, 2026.
Position: ML Conferences Should Establish a Refutations and Critiques Track
R. Schaeffer, J. Kazdan, Y. Denisov-Blanch, B. Miranda, M. Gerstgrasser, S. Zhang, A. Haupt, I. Gupta, E. Obbad, J. Dodge, et al.
Advances in Neural Information Processing Systems (Position Paper), 2025.
Scaling Human Judgment in Community Notes with LLMs
H. Li, S. De, M. Revel, A. Haupt, B. Miller, K. Coleman, J. Baxter, M. Saveski, M.A. Bakker
Journal of Online Trust and Safety 3 (1), 2025.
AI should not be an imitation game: Centaur evaluations
A. Haupt, E. Brynjolfsson
International Conference on Machine Learning (Position Paper), 2025.
In brief
Standalone benchmarks reward AI for replacing people. Centaur evaluations instead measure what a human–AI team achieves—the uplift over either alone—and thereby make human-centred properties (interpretability, helpfulness, complementarity) first-class objectives rather than afterthoughts. The paper argues that such evaluations are both more demanding and more realistic than current leaderboards, and sets out a research program: who the humans are, how to randomize access, how to score teams. It is the conceptual basis for AlignmentBench (interview-then-predict), SimulacraBench, and the AI-oral-assessment study.
Convex Markov Games: A New Frontier for Multi-Agent Reinforcement Learning
I. Gemp, A. Haupt, L. Marris, S. Liu, G. Piliouras
International Conference on Machine Learning, 2025.
In brief
Multi-agent reinforcement learning assumes rewards add up over time. Many objectives do not: diversity, imitation, fairness, safety. Convex Markov games let players hold general convex preferences over occupancy measures, strictly generalizing Markov games (including infinite horizon). Pure-strategy Nash equilibria exist, and we approximate them by gradient descent on an exploitability bound. In the prisoner's dilemma, "transient imitation" recovers a profile close to human play with higher utility and roughly a thousand-fold lower exploitability; experiments also show fairer coordination and safer robot-warehouse behaviour.
Risk Preferences of Learning Algorithms
A. Haupt‡, A. Narayanan‡
Games and Economic Behavior 148, p. 415-426, 2024.
In brief
Standard bandit algorithms are not risk-neutral. ε-greedy learning is emergently risk-averse: between two actions with equal expected payoff it picks the lower-variance one with probability approaching one, and transiently even when the riskier action is strictly better on average. In a recommender or marketplace this favours measurable, homogeneous options and produces inequity and homogenization. Two corrections—reweighting data by how often an action was chosen, or optimistic estimates for rarely-chosen actions—restore risk neutrality.
Formal Contracts Mitigate Social Dilemmas in Multi-Agent Reinforcement Learning
A. Haupt‡, P. Christoffersen‡, M. Damani, D. Hadfield-Menell
Autonomous Agents and Multi-Agent Systems 38, Article 51, 2024.
In brief
Add a contracting stage to a Markov game—agents can voluntarily bind themselves to reward transfers—and, with a rich enough contract space, every subgame-perfect equilibrium of a fully observable Markov game is socially optimal; richer spaces weakly raise welfare in general, including under partial observability. The MOCA algorithm makes this learnable, validated in traffic, pollution, and common-pool-resource environments.
Steering No-Regret Learners to a Desired Equilibrium
B.H. Zhang, G. Farina, I. Anagnostides, F. Cacciamani, S.M. McAleer, A. Haupt, A. Celli, N. Gatti, V. Conitzer, T. Sandholm
ACM Conference on Economics and Computation, 2024.
Certification Design for a Competitive Market
A. Haupt‡, N. Immorlica‡, B. Lucier‡
ACM Conference on Economics and Computation, 2024.
In brief
Certification is the market's answer to unobservable quality, from carbon credits to educational tests to AI models. We study a certifier that designs and prices certificates while sellers choose both quality and certificate and prices form competitively. Under single crossing, sellers' certification choices are uniquely pinned down; the revenue-maximizing certifier's problem reduces to monopoly pricing with non-linear valuations, for which we give an FPTAS; and both welfare- and revenue-optimal certificate menus can be arbitrarily large.
Black-Box Access is Insufficient for Rigorous AI Audits
S. Casper, C. Ezell, C. Siegmann, N. Kolt, T.L. Curtis, B. Bucknall, A. Haupt, K. Wei, J. Scheurer, M. Hobbhahn, et al.
ACM Conference on Fairness, Accountability, and Transparency, 2024.
Computing Optimal Equilibria and Mechanisms via Learning in Zero-Sum Extensive-Form Games
B. Zhang, G. Farina, I. Anagnostides, F. Cacciamani, S. McAleer, A. Haupt, A. Celli, N. Gatti, V. Conitzer, T. Sandholm
Advances in Neural Information Processing Systems, 2023.
Understanding Multi-Homing and Switching by Platform Drivers
X. Guo‡, A. Haupt‡, H. Wang, R. Qadri, J. Zhao
Transportation Research Part C: Emerging Technologies 154, 2023.
Towards Psychologically-Grounded Dynamic Preference Models
M. Curmei‡, A. Haupt‡, B. Recht, D. Hadfield-Menell
ACM Conference on Recommender Systems, 2022.
The Optimality of Upgrade Pricing
D. Bergemann‡, A. Bonatti‡, A. Haupt‡, A. Smolin‡
Web and Internet Economics, 2021.
Ongoing Work
TaskNet task bags from AI-guided interviews Work AI Evaluation
Economic Evaluations measurement science of economically relevant tasks Work AI Evaluation
AlignmentBench alignment as a centaur evaluation Work AI Evaluation Preferences
SituatedEvals competitions in predicting real-world microdata AI Evaluation Preferences
Design for Disobedience algorithmic monoculture as a benchmark AI Evaluation Preferences
VZBVal consumer protection evaluations in the German context Platforms Market Design AI Evaluation
The Role of Roles in contextual integrity Privacy Preferences
Vita
A Resume, a Computer Science-style CV and an Economics-style CV are available as pdf; their LaTeX source uses this site’s style.
-
Schmidt Sciences Aug 2026-Aug 2027AI Institute Fellow-in-Residence
AI Institutes -
Stanford Digital Economy Lab Aug 2026-Aug 2027Digital Fellow
Stanford Institute for Human-Centered AI -
Harvard Kennedy School Aug 2026-Aug 2027Technology and Human Rights Fellow
Harvard Kennedy School -
Stanford University 2024-2026Human-Centered AI Fellow
Stanford Impact Labs Fellow
Departments of Computer Science and Economics
HAI, DEL, StatsML, CRFM, STAIR
Co-Chair, Stanford HAI Affinity Group on Global AI Governance
Rising Star in Data Science, 2025
Young Scientist, 8th Economics Lindau Nobel Laureate Meeting, 2025
Young Researcher, 12th Heidelberg Laureate Forum, 2025 -
MIT 2019-2024Ph.D. Student
Engineering-Economic Systems, Computer Science and AI Lab
Committee: A. Bonatti, D. Hadfield-Menell, E. Maskin, D. Parkes
Co-Chair, MIT AI Ethics and Policy Group
Vice-President, MIT Science Policy Initiative
Price Theory Summer Camp, Becker Friedman Institute, 2024 -
Summer Fellow
Office of International Affairs
Bureau for Competition -
European Commission Jan-May 2021Atypical Trainee
Directorate-General for Competition -
Berufliche Schulen Gross-Gerau 2017-19Teach First Deutschland Fellow
Full-time high school teaching -
University of Frankfurt 2017-19B.S. Student
Computer Science Department -
University of Bonn 2015-18M.S. Student (distinction)
Economics Department -
University of Bonn 2014-17M.S. Student
Mathematics Department
Year 1 at EPF Lausanne
Years 2-3 at Bonn -
University of Bonn 2012-14B.S. Student
Mathematics Department